 ARCH POINT RECOVERY
Buying guide · Updated 2026-09-22
Buying a used NVIDIA A100 40GB SXM4 rack in 2026
A used A100 rack can suit an engineering team with steady workloads, a compatible facility and the ability to commission secondhand hardware. This offer is $155,000 per complete rack, seller-stated, FOB Texas, subject to confirmation. The supplied BOM describes four eight-GPU servers and three utility servers: 32 A100 40GB SXM4 GPUs, 1,280 GB aggregate HBM and approximately 4.67 TB system RAM. Arch Point Recovery has not tested these racks.
See the listing and current availability. Photos establish physical context, not operational status.
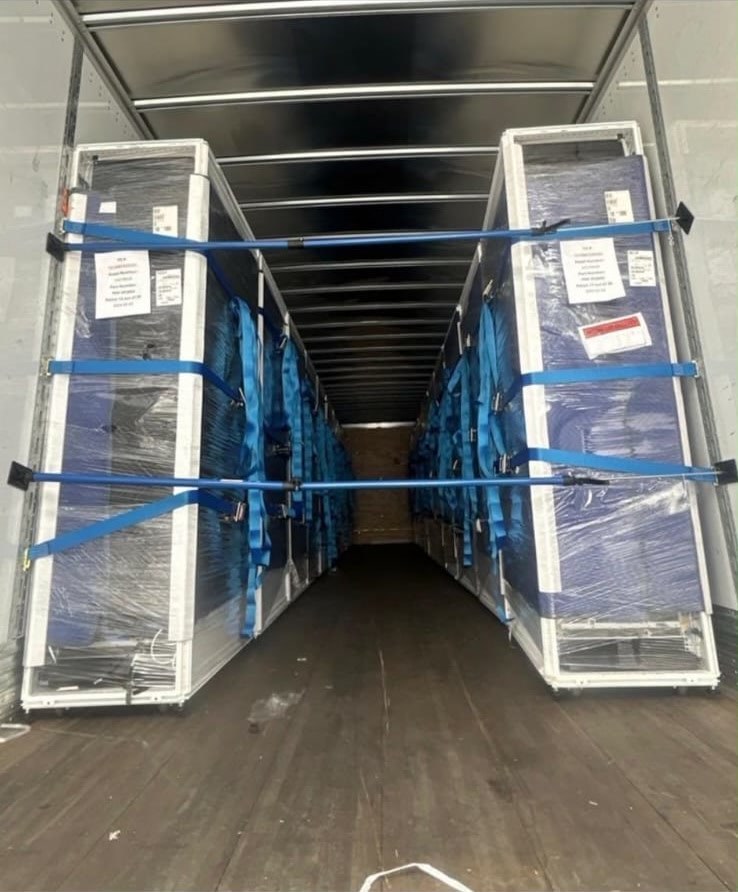
What an HGX rack gives you
SXM4 modules mount on a server baseboard rather than behaving like interchangeable PCIe cards. NVIDIA’s HGX A100 software guide, October 2020 describes NVSwitch connectivity within an eight-GPU HGX system. That makes each server a useful multi-GPU building block; four servers do not automatically become one uniformly connected 1.28 TB GPU.
The NVIDIA A100 datasheet provides the architecture reference. The BOM specifies dual 64-core Rome processors per server; AMD’s EPYC 7002 family datasheet explains the generation, but does not identify this lot’s exact CPU SKU.
Potential 2026 uses include private inference, LoRA fine-tuning, research queues and sovereign or regional clouds where data locality matters. An edge installation still needs datacenter power, cooling and trained operators. Buyers needing very large context windows or minimal administration should compare newer GPUs and managed cloud service.
WCS, ZT Systems and the network question
Microsoft WCS / ZT Systems denotes a hyperscale-oriented rack design. Confirm chassis dimensions, replacement parts, rack-manager access and provisioning before treating it as conventional enterprise equipment. The GPU-server BOM lists 54 V PSU output; this is not the facility input-voltage specification.
OCP’s Project Olympus design library, contributed in 2017, documents rack, power and management interfaces. It is background for due diligence, not proof that these particular racks meet every Olympus specification or run retail firmware.
The BOM lists 32 ConnectX-6 200GbE adapters. NVIDIA’s ConnectX-6 manual explains adapter capability. However, the included Arista 7060CX-32S has 32 100GbE ports. A complete 200GbE fabric, optics inventory, RoCE configuration and inter-rack switching are unconfirmed. This distinction affects distributed training substantially.
What published deployments and reviews establish
- Microsoft’s ND A100 v4 launch, June 1, 2021 reported 16.59 PFLOPS HPL across 164 VMs. That demonstrates an engineered A100 deployment, not the performance or provenance of this lot.
- Lambda’s A100 TCO study, September 22, 2021 compared eight-GPU 40GB SXM4 servers with PCIe systems and cloud rental. Its useful lesson is that occupancy and interconnect change economics; its historical prices are not current quotes.
- Hugging Face’s BLOOM engineering report, July 2022 describes training on 384 A100 80GB GPUs. It illustrates the software and communication work required at scale; those larger-memory GPUs are not equivalent to this 40GB lot.
- ServeTheHome’s hands-on cooling comparison, August 2, 2021 measured 5,164 W for an eight-A100 40GB air-cooled server under Linpack. That is a useful facility-planning reference, not a measurement of these WCS servers.
The MLPerf Training v1.0 archive, June 2021 includes an eight-A100 SXM4 Inspur configuration. Its successful BERT run 10 took approximately 18.94 minutes. This is one submitted run, not an aggregate score; it used 80GB, 500W GPUs and liquid cooling. It does not predict this 40GB rack’s results.
What can run: memory and throughput estimates
The following are planning estimates, not lot benchmarks. Weight memory is parameters multiplied by bytes per weight; quantization metadata, activations, framework buffers and KV cache require extra space. GPU counts below are weight-only minima, not deployment guarantees.
| Open-model class | FP16 weights / GPUs | INT8 weights / GPUs | INT4 weights / GPUs |
|---|---|---|---|
| Mistral 7B | 14 GB / 1 | 7 GB / 1 | 3.5 GB / 1 |
| Llama 3 8B | 16 GB / 1 | 8 GB / 1 | 4 GB / 1 |
| Llama 2 13B | 26 GB / 1 | 13 GB / 1 | 6.5 GB / 1 |
| Llama 70B class | 140 GB / 4 | 70 GB / 2 | 35 GB / 1, very tight |
Two GPUs give smaller models more cache and batching headroom. Four can hold 70B FP16 weights; eight provide more working space within one HGX node. For 70B INT4, plan to evaluate two GPUs rather than assuming one 40GB card leaves enough cache. Model licenses and quantized-kernel support also need review.
Argonne’s 2024 LLM-Inference-Bench study tests A100 SXM 40GB. Approximate chart readings at 1,024 input/output tokens in FP16 give 1,500 tokens/s for Llama-2-7B and 3,500–4,000 for Mistral-7B or Llama-3-8B on one GPU with TensorRT-LLM at batch 64. Four-GPU 70B results are roughly 300–700 tokens/s, depending on model, framework and batch; batch-one Llama-3-70B is around 55–60 tokens/s. These are benchmark throughput estimates, not per-user chat speeds or current-version guarantees.
For independent Mistral inference replicas, mechanically multiplying 3,500–4,000 by 32 gives 112,000–128,000 aggregate tokens/s per rack, or 2.24–2.56 million for 640 GPUs. These optimistic capacity estimates assume equally loaded replicas and adequate CPU, storage and networking. They do not predict one distributed model’s speed.
Fine-tuning, pre-training and other workloads
For LoRA/QLoRA, estimate 7B/13B experiments on one 40GB GPU with controlled sequence lengths and batches; a 70B adapter run should be evaluated across several GPUs. The QLoRA paper, May 2023 demonstrated a 65B model on 48GB, which does not establish a 40GB fit. Mixed-precision Adam memory accounting gives a planning allowance near 18 bytes/parameter before activations: approximately 126 GB for 7B and 234 GB for 13B. Estimate four and eight GPUs respectively with sharding and checkpointing; benchmark the actual recipe.
NVIDIA rates dense FP16 Tensor Core compute at 312 TFLOPS/GPU. For an assumed 40–50% model FLOPS utilization, estimate tokens/day as GPUs × 312e12 × utilization × 86400 / (6 × parameters). Karpathy’s published A100 training log, 2024 reports about 40% MFU on a much smaller GPT-2 run; it motivates a sensitivity case, not a measured 7B/13B rack result. The 50% endpoint is optimistic.
| Estimated dense pre-training | 32 GPUs | 640 GPUs, ideal scaling |
|---|---|---|
| 7B tokens/day | 8.2–10.3 billion | 164–205 billion |
| 13B tokens/day | 4.4–5.5 billion | 88–111 billion |
Attention overhead, failed jobs, checkpointing and the unresolved fabric reduce practical totals. For diffusion, Lambda’s October 2022 benchmark measured roughly seconds per 512×512 image on A100 80GB PCIe. Using a conservative five-second scenario gives an estimated 6.4 images/s per rack or 128 per truckload with independent workers; this is not an SDXL/Flux benchmark or a measured 40GB result.
For HPC, peak arithmetic estimates are 310.4 TFLOPS conventional FP64 per rack, or 624 TFLOPS FP64 Tensor Core for compatible matrix operations. Twenty racks multiply these to 6.208 and 12.48 PFLOPS respectively. Sustained application performance will be lower.
Inspection checklist and operating cost
Before purchase, request:
- Exact CPU SKU, GPU-server SSD capacities and confirmation every rack matches the BOM.
- Serial inventory and GPU diagnostics, ECC history, burn-in and working-status evidence.
- Rack input voltage, phases, connectors, measured draw, airflow and cooling requirements.
- BIOS/BMC credentials, firmware state and release from Microsoft-specific provisioning restrictions.
- Switch software, transferable licensing, optics, cabling and the actual network topology.
- Warranty/DOA terms, inspection rights, Texas pickup location and rigging/freight responsibilities.
GPU nameplate power alone is an estimated 12.8 kW/rack: 32 × 400 W. Allow an initial 22–26 kW IT-load scenario for servers, fans and switches, informed by the comparable server measurement above; 20 racks imply 440–520 kW IT load, before cooling overhead. The seller must confirm facility requirements.
Lambda’s cloud price reference, checked September 22, 2026, lists A100 SXM 40GB at $1.99/GPU-hour, excluding applicable taxes. Estimated 32-GPU equivalent rental is $63.68/hour, or $45,850 per 720-hour month at continuous use. At 25% utilization it is about $11,462/month, assuming capacity is available when needed.
An estimated 24 kW rack at $0.10/kWh and PUE 1.3 costs about $2,246/month in electricity. Add freight, commissioning, colo, staff, repairs, storage, fabric upgrades and financing. The $155,000 purchase equals about 2,434 cloud rack-hours before operating costs, not a payback forecast. Hashrate Index’s April 8, 2026 market analysis distinguishes public asks from private transactions; resale value should not be assumed.
Seller-stated lot-size math
| Scenario | Racks | GPUs | GPU / utility servers | Asking total |
|---|---|---|---|---|
| One rack | 1 | 32 | 4 / 3 | $155,000 |
| Seller-stated truckload | 20 | 640 | 80 / 60 | $3,100,000 |
| Seller-stated three truckloads | 60 | 1,920 | 240 / 180 | $9,300,000 |
These are arithmetic scenarios. The source subject references 20 racks while the message mentions three truckloads. 60 racks are not confirmed inventory; current quantity and single-rack purchasing require confirmation.
FAQ
Are these 80GB A100 GPUs?
No. The supplied BOM specifies A100 40GB SXM4 modules.
Is the rack tested and ready to deploy?
Working condition, management access and facility compatibility remain unconfirmed. Arrange acceptance testing.
Can a 70B model run?
Four GPUs can hold approximately 140 GB of FP16 weights. Cache and runtime overhead may require additional GPUs or reduced context and concurrency.
Is 1.28 TB available to one GPU?
No. It is aggregate memory across 32 devices. Software must distribute the workload.
Is the included network 200GbE throughout?
That is unconfirmed. The adapters are specified at 200GbE; the included Arista model has 100GbE ports.
Can I buy a single rack?
Request confirmation. Seller-stated shipping groups are 20 racks, but the minimum purchase is unresolved.
What should I send with an inquiry?
Send quantity, destination, timeline, workload and required testing terms, referencing lot-37bf0c202ad0.
Request the technical package
Review the hardware listing, browse inventory, or email Arch Point Recovery for current availability and the documents needed to evaluate this lot.